When you are the only one
The recovery steps that live in one person's head
If you are the only person who can recover the cluster, a week off is a company risk. We work the same systems you do: Proxmox and KVM, ZFS and Ceph and GlusterFS, Pacemaker clusters, Postgres and MySQL. The point is coverage, so the estate is not a one-person job.
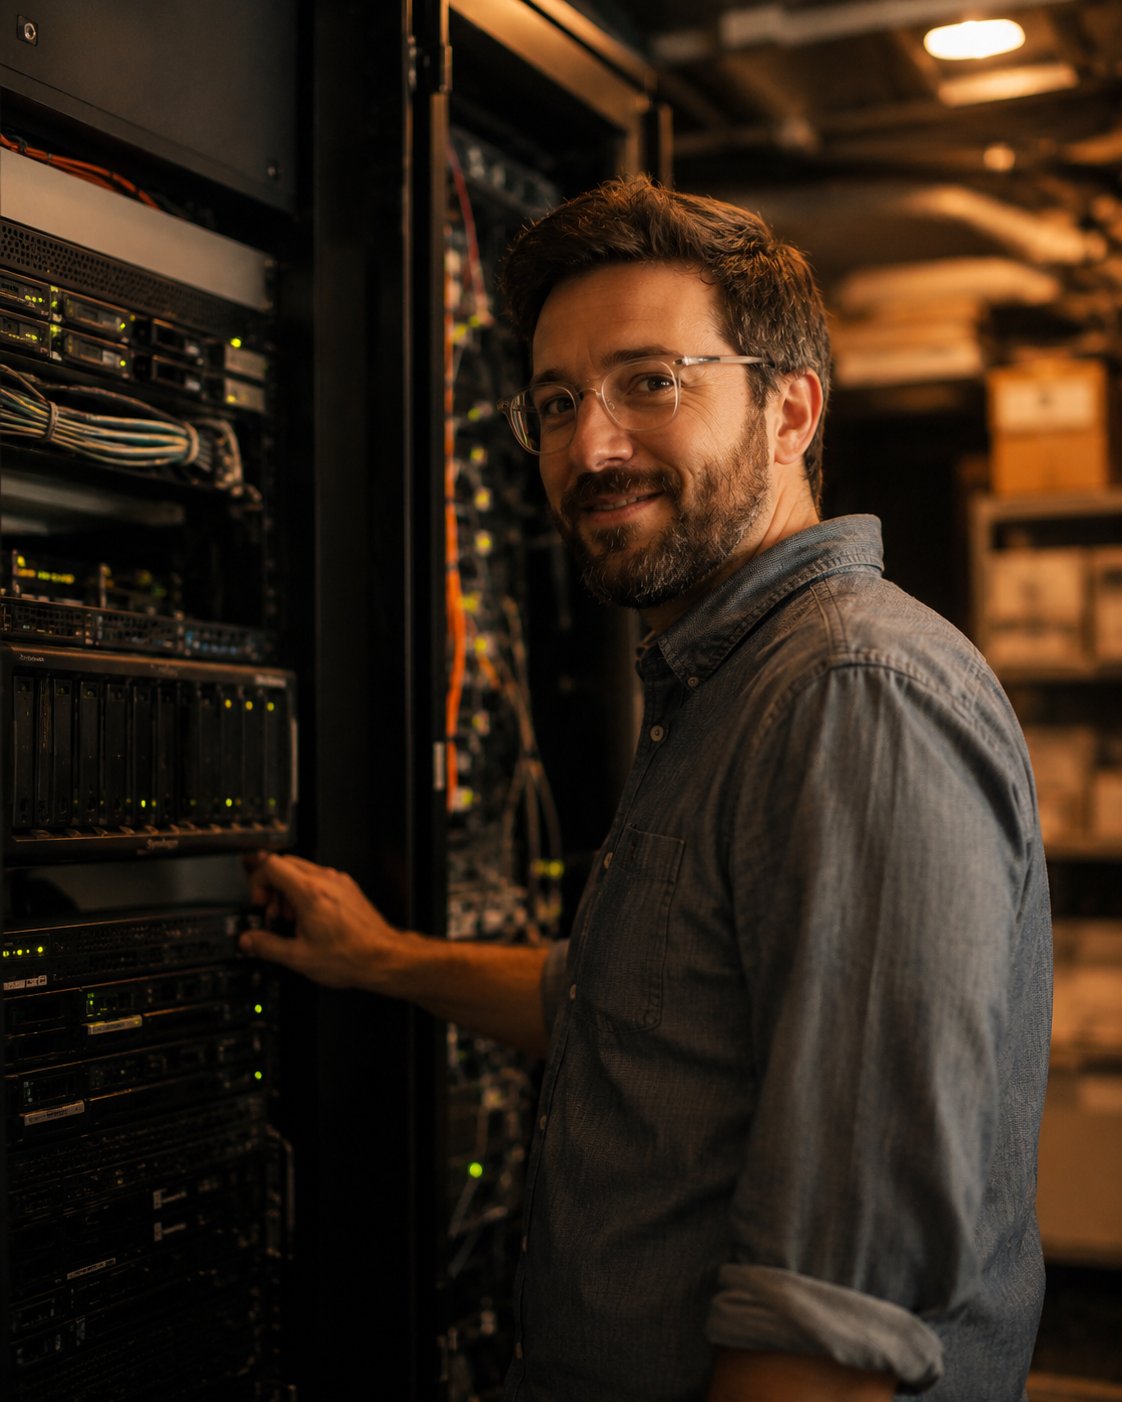
The recovery steps that live in one person's head
Incidents still happen when you are out. Someone has to be able to pick them up.
Storage, filesystems, clustering and Linux virtualization
Distribution upgrades under applications nobody wants to touch
The work that lives in one person's head, and the risk if they leave.
Reduce downtime risk on systems where every minute of outage carries compliance exposure, public impact, or constituent trust.
Learn more >
Cutovers, hyperscaler moves, and tenant-safe maintenance windows that don't become surprise downtime for paying customers.
Learn more >
Modernizing aging Linux systems without disrupting transaction-processing windows or core banking schedules.
Learn more >
Tested failover, backup integrity, and recovery objectives that hold up under examiner scrutiny.
Learn more >
Visibility across heterogeneous Linux environments so incidents surface before outages show up for users, citizens, or downstream partners.
Learn more >
Platforms that have to stay up across sites, primary and DR, active-active or active-passive, with failover that has been tested, not assumed.
Learn more >
If only you can recover it, you cannot take a week off.
Someone else can pick it up. You can actually leave.
Someone who can take the page so a week off does not leave the company exposed.
Performance bottlenecks, filesystem and storage behaviour, and configuration problems that do not resolve from a runbook.
Upgrades and maintenance planned around dependencies and downtime, so the fix does not become the next incident.
Clustering, high availability, distributed storage and Linux virtualization, which are the areas it is hardest to stay current in on your own.
Automation, configuration management and monitoring that take recurring tasks off your week.
Direct technical conversation and documentation you keep, so the knowledge is not only in your head.
Real engagements, real outcomes.
How the American Dairy Goat Association migrated off AWS, upgraded Oracle, and got back to their mission, on a non-profit budget.
How Follosoft stopped firefighting Linux infrastructure and got back to building their field-operations platform.
How Crafty Penguins delivered a fully production-ready, high-availability, multi-data-center platform for a US commercial bank, from zero footprint to documented handover.
What this work looks like in practice.
A short call with an engineer. Tell us what only you can do and we will tell you what we would cover so you can leave.
Conversation first, scope second. No pressure.